A load balancer is a piece of hardware or software that sits in front of two or more servers and decides which one handles each incoming request. If one server is slow, full or down, the load balancer sends the work somewhere else. Visitors see one address and one website. Behind it, several machines share the job.
That is the short answer to “what is a load balancer”. The longer answer matters if you are the person who has to pick one, configure one or explain one to a manager. This guide covers how a load balancer works, the main types, the algorithms that choose a server, health checks, sticky sessions and the mistakes that cause outages. Where we quote specifics, they come from vendor documentation for AWS, NGINX and Cloudflare, linked in the text.
Our editorial view, up front: for most small teams the right load balancer is the one built into the platform they already use. Self-managed software such as NGINX or HAProxy earns its place when you need control over routing rules or you run your own servers. A hardware appliance is rarely the first answer in 2026. Documentation was reviewed on October 20, 2026. Treat product limits and defaults as things to recheck before you build.
1. What is a load balancer, and why do sites need one?
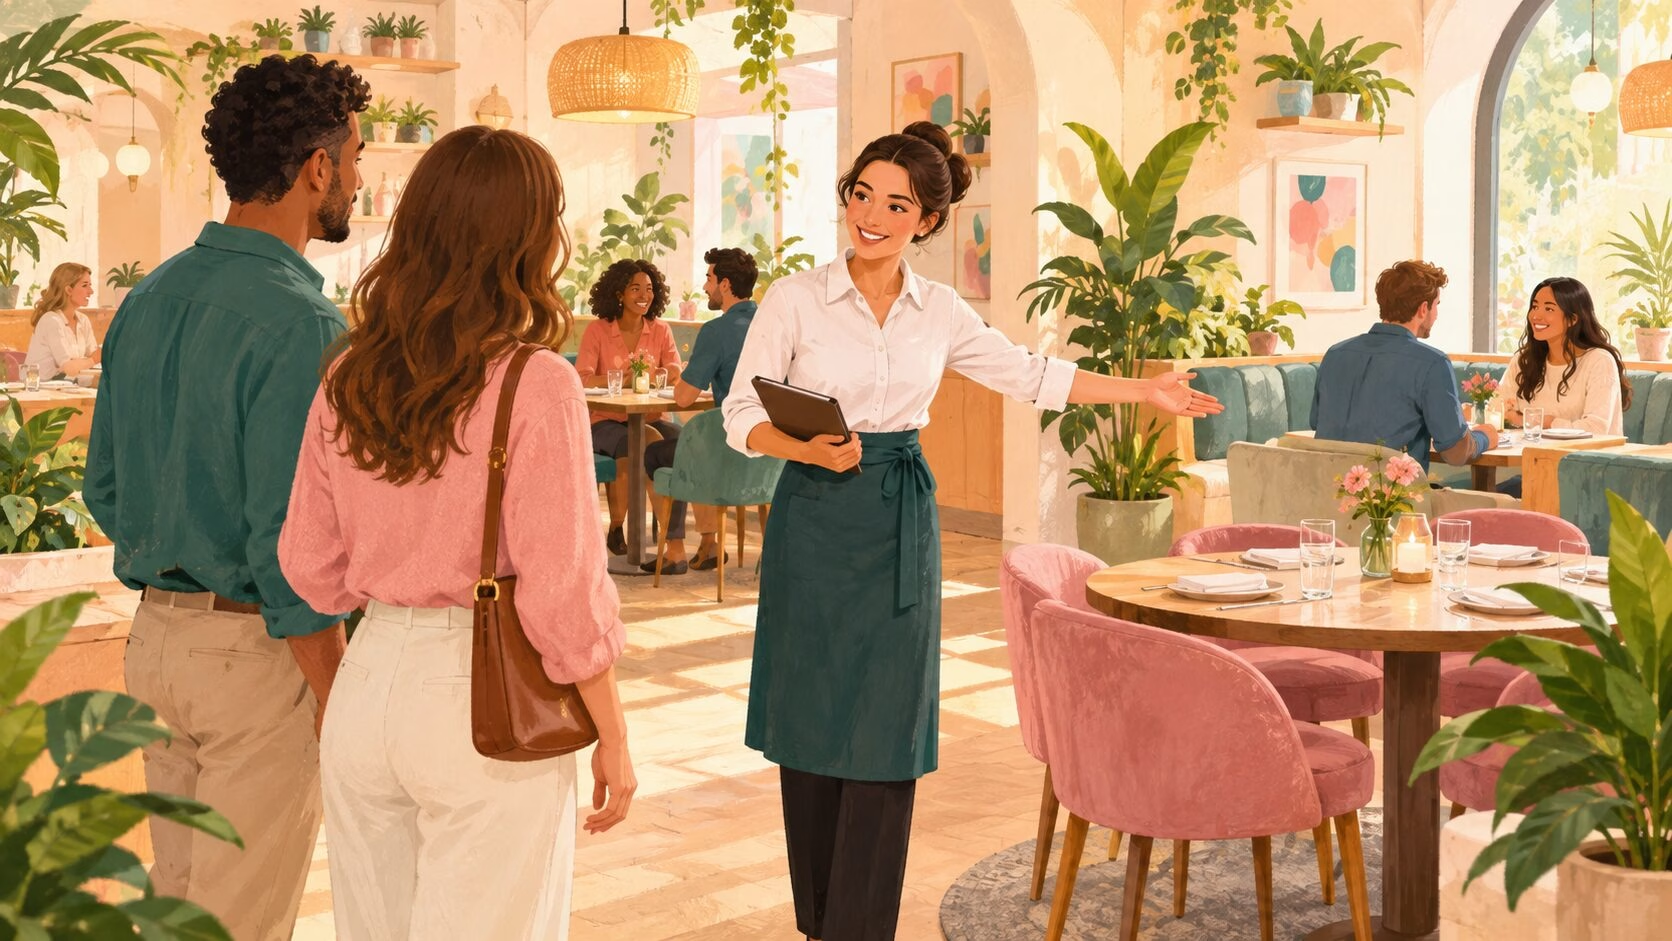
Think of a busy restaurant. Guests do not choose their own table. A host looks at the room, sees which sections are full and seats each party where there is space. If a section closes, the host stops sending people there. A load balancer plays the host for your servers.
The AWS documentation puts it plainly: Elastic Load Balancing distributes incoming traffic across multiple targets, such as EC2 instances, containers and IP addresses, in one or more Availability Zones, and it routes traffic only to the healthy targets. That one sentence contains the two jobs every load balancer does. It spreads traffic and it avoids broken servers.
Three practical benefits follow from those jobs:
- Availability. With one server, a crash means an outage. With three servers behind a balancer, a crash means slightly less capacity until the machine returns.
- Scalability. You can add or remove servers as demand changes without telling visitors to use a new address. AWS notes you can add and remove compute resources from your load balancer as your needs change without disrupting the overall flow of requests.
- Maintenance without downtime. You can drain one server, patch it, return it to the pool and repeat. This is a quiet reason many teams adopt a balancer, and it fits well with DevOps habits such as frequent releases.
Cloudflare describes load balancing as distributing network traffic among multiple servers to improve a service’s performance and reliability, which also cuts latency because no single server carries all the strain. Not every site needs one. A brochure site on a single managed host can run for years without it. The need appears when downtime costs real money, when traffic spikes are normal, or when one machine can no longer keep up. A delivery app like DoorDash has all three problems on a Friday evening, which is why delivery and checkout flows are usually the first parts of a product to sit behind a balancer.
2. How a load balancer works, step by step
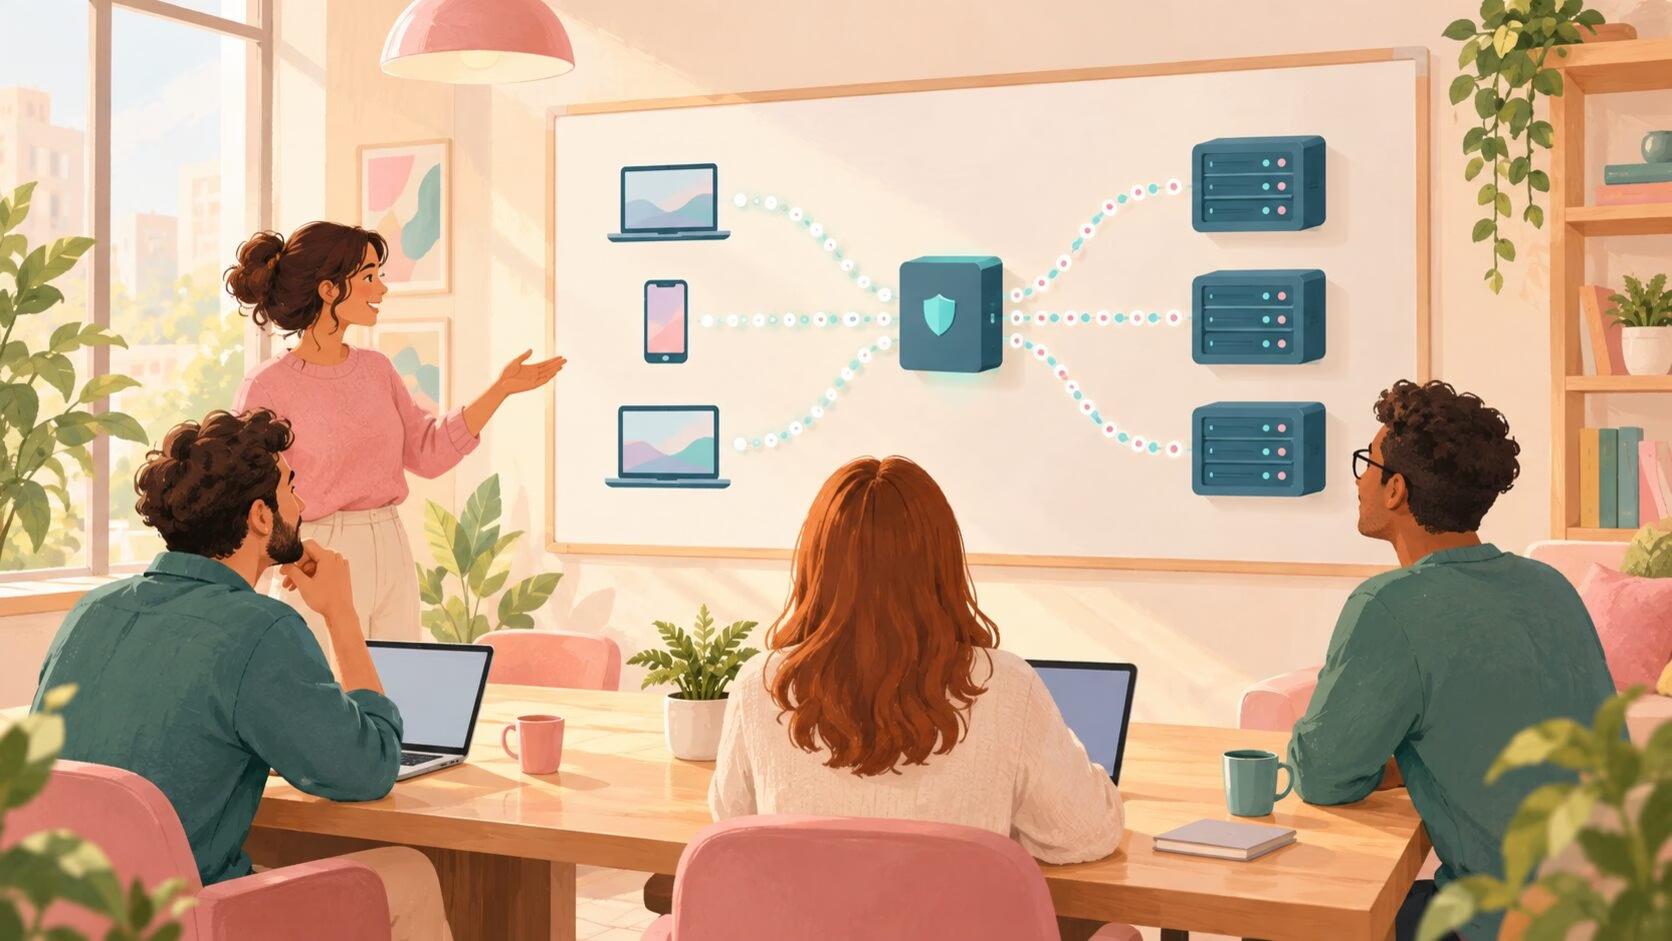
The mechanics are simpler than the vocabulary suggests. Here is the path of one request through a typical setup.
- The visitor connects to one address. DNS points your domain at the load balancer, not at any individual server.
- The load balancer receives the request. Depending on the type, it may only look at network details such as IP address and port, or it may read the full web request, including the path and headers.
- It picks a target. A rule or algorithm chooses one server from a pool, often called a target group or upstream group. We cover the algorithms in section 5.
- It forwards the request and returns the response. The visitor never sees which server answered.
- It keeps watching. Health checks run in the background. A server that fails them stops receiving new traffic until it recovers.
Two details are worth knowing. First, many balancers can also offload encryption. AWS notes that you can hand the work of encryption and decryption to the load balancer so that your compute resources can focus on their main work. That reduces CPU use on the application servers, but it also means the balancer becomes a place where traffic is decrypted, so treat its configuration as part of your security surface. If that topic is new, our guide to endpoint security covers the wider habits, and cybersecurity in digital transformation explains why traffic entry points deserve attention.
Second, the load balancer itself must not become the single point of failure. Managed cloud balancers run as several nodes across zones. AWS says Elastic Load Balancing creates a load balancer node in each Availability Zone you enable. On your own servers, the usual answer is a pair of balancers with failover, so the host is never alone.
3. Types of load balancers: hardware, software and cloud
Cloudflare notes that a load balancer can be hardware-based or software-based. In practice, three delivery models cover almost every real deployment.
Hardware load balancers
These are dedicated appliances installed in a data center. They suit large organizations with strict performance or compliance needs and a team that can maintain them. Cloudflare describes the traditional approach in large local networks as using application delivery controllers or dedicated devices. The trade-offs are purchase cost, rack space, firmware upgrades and limited flexibility if your traffic pattern changes. For a startup or a small business, this is usually the wrong starting point.
Software load balancers
Software balancers run on an ordinary server, virtual machine or container. NGINX and HAProxy are the best-known open-source examples. The NGINX guide says the software can act as a very efficient HTTP load balancer to improve performance, scalability and reliability of web applications. You control the configuration, which is both the appeal and the risk. A typo in a config file can take everything down, so version control and a test environment matter. If you run your own machines, our overview of VPS hosting on Linux and the notes on what a server costs for app hosting help you size the boxes. Tools such as CtrlOps can make routine server administration over SSH less scattered, and Loupe for Kubernetes gives a visual view of workloads if you run Kubernetes.
Cloud load balancers
Cloud providers sell balancing as a managed service. AWS, for example, offers several types and recommends current-generation ones: Application Load Balancers, Network Load Balancers and Gateway Load Balancers. It describes Classic Load Balancers as the previous generation and recommends migrating from them. The advantage is that capacity scales automatically and the provider handles the nodes. The cost is some lock-in, because rules and settings do not transfer neatly between clouds. This model overlaps with cloud computing generally: you rent a function instead of running it. If you host on a managed platform such as Render or a hosting provider such as Hostinger, check that provider’s own documentation to see how traffic reaches multiple instances before you plan a separate balancer.
4. Layer 4 vs Layer 7 load balancing
This is the distinction that confuses most beginners and it decides which product you need. The numbers refer to layers in the OSI networking model.
Layer 4 (transport) balancers route using network information: protocol, IP addresses and ports. They do not read the content of a web request. That keeps them fast. The AWS Network Load Balancer works at the fourth layer and, per its documentation, can handle millions of requests per second. It also supports static IP addresses, and you can assign one Elastic IP address per enabled subnet. For TCP traffic it chooses a target with a flow hash based on protocol, source and destination IP addresses and ports, plus the TCP sequence number.
Layer 7 (application) balancers read the web request itself and can route by URL path, host name, header, method or query parameter. The AWS Application Load Balancer works at the application layer and supports routing based on fields such as HTTP header conditions and methods, query parameters and source IP addresses. That lets one balancer send /api to one group of servers and /images to another, a common pattern when a site is split into services.
A simple rule of thumb from us: choose Layer 7 for websites and APIs, because content-aware routing and per-service health checks pay off quickly. Choose Layer 4 when you move non-web traffic, need fixed IP addresses or push extreme connection volumes. Many mature systems use both, with a Layer 4 balancer at the edge and Layer 7 inside. Teams building enterprise AI agents or other multi-service back ends hit the Layer 7 use case early, because each service tends to need its own routing and health rules.
5. Load balancing algorithms: round robin, least connections and the rest
The algorithm decides which server gets the next request. Cloudflare sorts them into two families. Static algorithms follow a fixed plan and ignore current server state. Dynamic algorithms consider the availability, workload and health of each server, which spreads work more fairly but is harder to configure.
Which should you pick? For a first deployment of a normal web app, leave round robin in place and measure. Move to least connections when you see uneven load, usually caused by a mix of fast page loads and slow downloads or report exports. Do not tune for a problem you have not observed. A good habit is to run a load test first. Our list of software testing tools is a reasonable place to find a tool for that, and a test should include one server being switched off mid-run so you see the result of failover too.
6. Health checks and failover: how a load balancer avoids broken servers
Distribution is only half the value. The other half is knowing when not to send traffic. Cloudflare explains that dynamic load balancers monitor servers with regular health checks. If a server is slow, it gets less traffic. If it fails, the load balancer reroutes to another group, a process called failover.
There are two styles, and the difference is worth understanding:
- Active health checks. The balancer sends test requests on a schedule, for example to a /health URL, and marks the server down after repeated failures. AWS configures these per target group, so each service can have its own check.
- Passive health checks. The balancer watches real traffic. In open-source NGINX, if a response from a server fails with an error, NGINX marks that server as failed and avoids it for a while. The max_fails directive sets how many consecutive failures count (the default is 1), and fail_timeout controls the window and how long the server stays marked. The NGINX guide notes that application health checks and activity monitoring are part of the paid NGINX Plus subscription, so open-source setups lean on passive checks unless you add something else.
Our advice: make the health check test something meaningful. A check that only confirms the web process answers can stay green while the database behind it is down. A good health endpoint verifies the dependencies the app genuinely needs, but it should be cheap and fast. A health check that runs a heavy query every few seconds creates its own load problem.
Failover also needs spare capacity. If three servers each run at 80 percent and one fails, the other two cannot absorb the load. Plan so that losing one machine still leaves headroom. AWS also describes zone-level behavior: with cross-zone load balancing off, each load balancer node sends traffic only to targets in its own zone, so capacity per zone matters. Backups matter here too. A balancer protects availability, not data. Keep your data protected with tools from our data backup tools category, such as Kopia, Duplicati or Backblaze Computer Backup.
7. Sticky sessions and session persistence
With round robin or least connections, two requests from the same visitor can land on different servers. NGINX says this plainly: there is no guarantee that the same client is always directed to the same server. For stateless apps that is fine. For an app that keeps a shopping cart or login state in one server’s memory, it breaks things. The visitor adds an item, the next request hits a different server and the cart looks empty.
There are three ways to deal with it:
- Make the app stateless. Store sessions in a shared database or cache so any server can answer. This is the cleanest long-term answer.
- Use sticky sessions. The balancer pins a client to one server. In AWS target groups, stickiness is a setting that is off by default. In NGINX, ip_hash is the built-in way to tie a client to a server.
- Use a mixed approach. Keep light stickiness for legacy parts while moving state out step by step.
Stickiness has a cost. It weakens even distribution, because a few heavy users can pile onto one server. It also complicates failover, because a pinned user loses their session when their server dies. Treat stickiness as a bridge for an old application, not a design goal. If your product handles payments or trading, such as a cryptocurrency exchange app, stateless design and careful failover testing are worth the effort from day one.
8. How to choose a load balancer, and mistakes to avoid
Start with your situation, not with product names. The table below maps common cases to a sensible first choice. These are editorial recommendations based on documentation, not benchmark results.
Mistakes we see most often
- One balancer, no backup. The balancer becomes the single point of failure. Use managed multi-zone services or a failover pair.
- Shallow health checks. A green check on a broken app sends visitors to errors.
- No spare capacity. Failover only works if the remaining servers can take the load.
- Sticky sessions as a crutch. They hide a state problem and uneven load builds quietly.
- Forgetting the data layer. Several app servers sharing one database simply move the bottleneck. A balancer does not fix a slow query.
- Skipping the failure test. Switch a server off during a test and watch what happens before a real incident does it for you.
If your team is outsourcing the work, ask vendors how they handle failover and health checks. Our guide on IT consulting for cybersecurity lists the kinds of questions worth asking. For the basics of the hosting side, the app hosting and cloud computing glossary pages are a good short refresher, and virtual desktop services shows another place where connection brokering and balancing quietly do their work.
9. Load balancer FAQs
What is a load balancer in simple terms?
A load balancer is the traffic director for a group of servers. Every visitor request arrives at the load balancer first. It chooses a healthy server, passes the request along and returns the answer. If a server breaks, it stops sending traffic there. The visitor sees one working website and never needs to know how many machines sit behind it. It can be a hardware appliance, software such as NGINX or a managed cloud service.
What is the difference between a load balancer and a reverse proxy?
The two overlap. A reverse proxy sits in front of servers and forwards requests to them. A load balancer is a reverse proxy that spreads requests across several servers and tracks their health. NGINX shows the overlap well: its documentation describes the same software as a reverse proxy implementation that includes load balancing for HTTP, HTTPS, FastCGI, uwsgi, SCGI, memcached and gRPC. With a single backend server, you have a reverse proxy. With several, it is doing load balancing too.
Do I need a load balancer for a small website?
Usually not at the start. A single well-sized server or managed host handles many small sites, and a balancer adds cost and complexity. Add one when a single machine can no longer keep up, when you cannot accept downtime during updates, or when you want redundancy across zones. Before then, caching, image compression and a content delivery network often deliver more benefit for less effort.
Which load balancing algorithm is best?
There is no universal winner. Round robin is the default in NGINX and in AWS Application Load Balancer target groups, and it works well when servers are alike and requests are similar. Least connections suits uneven request lengths. IP hash or sticky sessions help with state held on a server. Measure your traffic, change one thing at a time and compare. Treat any claim of a single best algorithm with caution.
What happens if the load balancer itself fails?
That is the risk to plan for. Managed cloud balancers reduce it by running nodes in several zones, and AWS creates a node in each Availability Zone you enable. With self-managed software, run at least two balancers with failover so one can take over. Also monitor the balancer, because a silent failure there takes down every service behind it.
Is a load balancer the same as a CDN?
No. A load balancer spreads requests across your own servers. A content delivery network (CDN) caches content at many locations near visitors. They work well together, and Cloudflare notes that CDNs often include load balancing features. For a content-heavy site, a CDN may lower server load enough that you need fewer servers behind the balancer.
Sources: Elastic Load Balancing documentation from AWS, the NGINX load balancing guide and the Cloudflare learning article on Cloudflare load balancing. Defaults and available settings change, so recheck the vendor pages before you configure production systems.