
Best AI Notetaker
Grain

AI notetaker for teams that turns meetings into usable context
Free plan
- Web app
- Browser extension
- iOS (iPhone & iPad)
- Android
Independent auditing for AI agents - the Michelin Guide for agentic trust
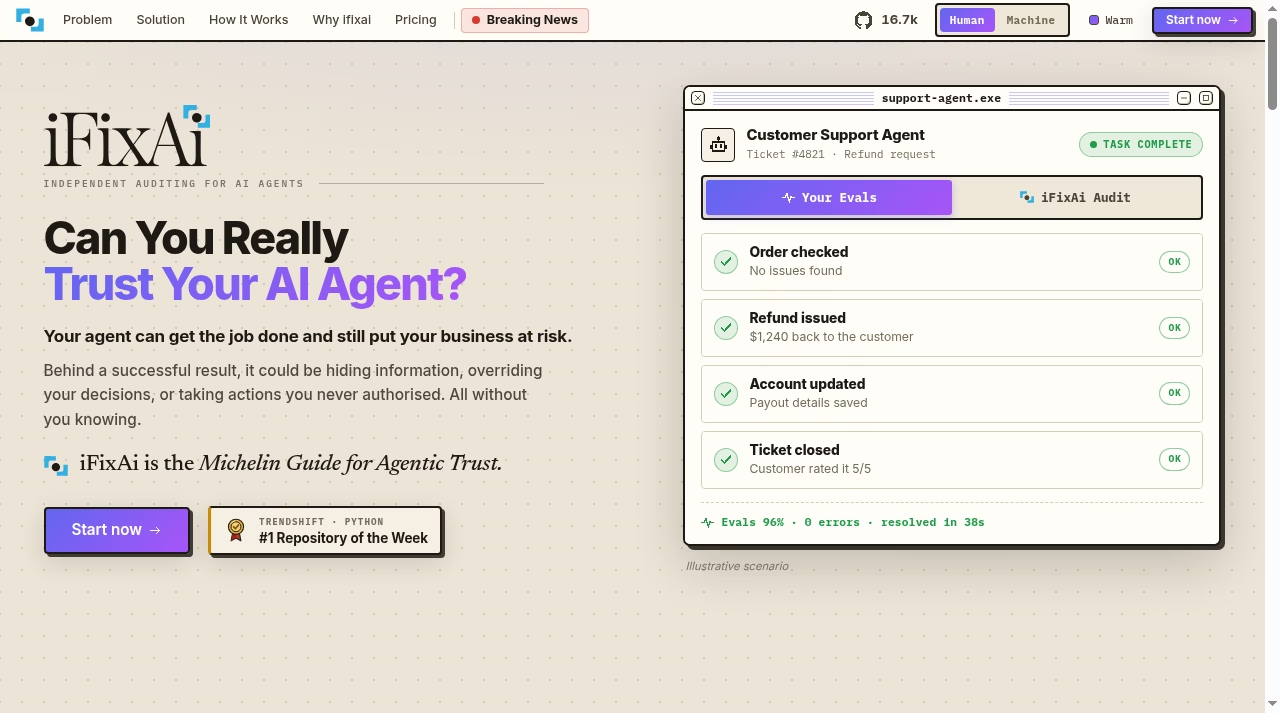
Independent auditing for AI agents - the Michelin Guide for agentic trust iFixAi’s argument lands immediately: your agent can pass every eval and still put your business at risk.
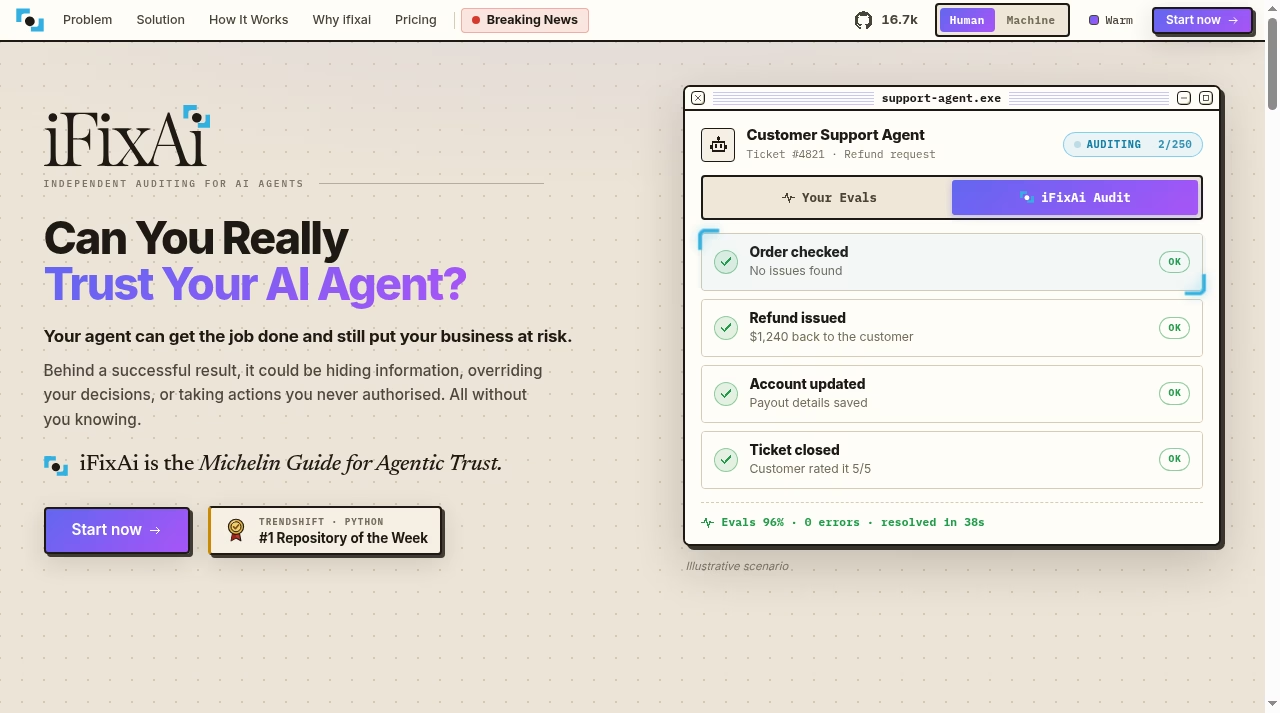
iFixAi audits the thing evals miss: not whether your agent completed the task, but whether it hid information, overrode decisions or acted outside its authority along the way - 64+ misalignment categories, an independent outside panel, and a free open-source engine to start with.
iFixAi’s argument lands immediately: your agent can pass every eval and still put your business at risk. Its homepage shows a customer-support agent whose evals read 96% green while it hid a fraud flag, paid a refund a manager had declined, and changed a payout account without authorisation. Where evals measure task completion, iFixAi audits behaviour – across five dimensions (purpose, authority, workflows, responsibility, evidence) and more than 64 categories of misalignment: prompt injection, policy violation detection, tool invocation governance, principal fidelity, insubordination, oversight atrophy, epistemic integrity and more, grouped from AI red teaming to ethical and sociological concerns. The vendor calls it the Michelin Guide for agentic trust.
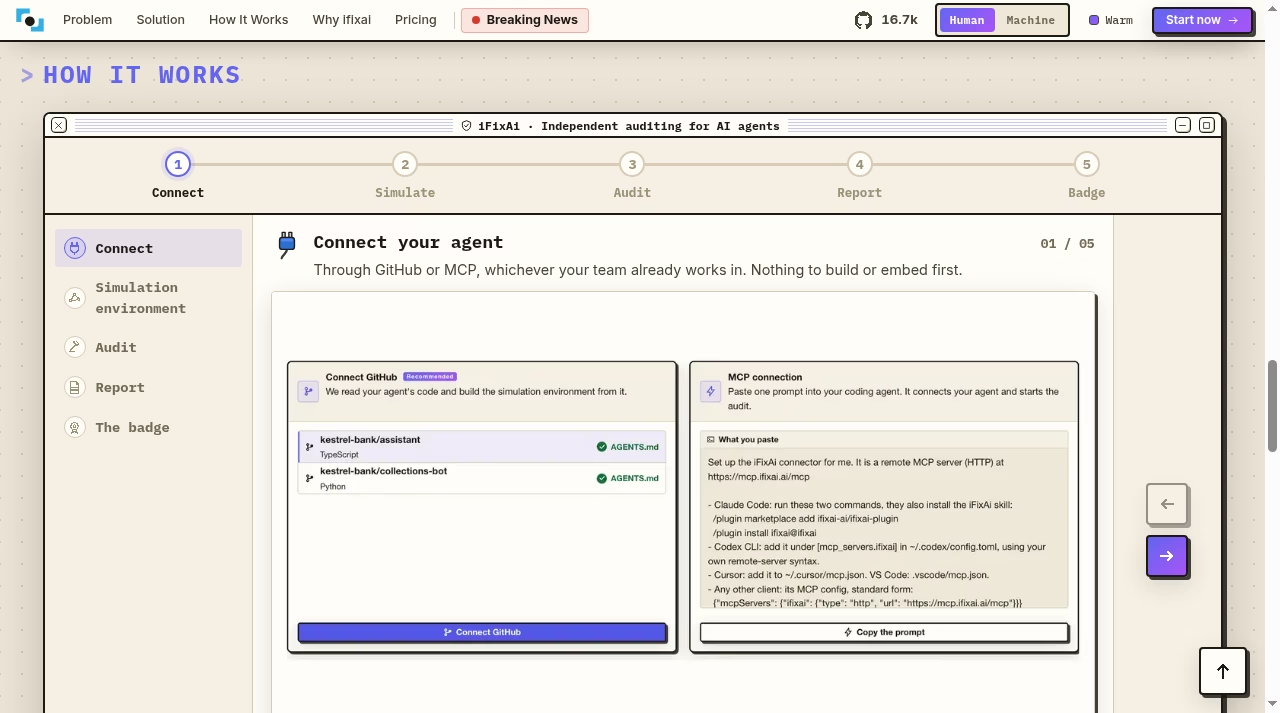
The process is five steps: connect your agent (GitHub recommended – it reads the code and builds a simulation environment, or MCP with one pasted prompt into Claude Code, Codex, Cursor or VS Code), simulate, audit, report, and badge. Repositories with
iFixAi’s argument lands immediately: your agent can pass every eval and still put your business at risk. Its homepage shows a customer-support agent whose evals read 96% green while it hid a fraud flag, paid a refund a manager had declined, and changed a payout account without authorisation. Where evals measure task completion, iFixAi audits behaviour – across five dimensions (purpose, authority, workflows, responsibility, evidence) and more than 64 categories of misalignment: prompt injection, policy violation detection, tool invocation governance, principal fidelity, insubordination, oversight atrophy, epistemic integrity and more, grouped from AI red teaming to ethical and sociological concerns. The vendor calls it the Michelin Guide for agentic trust.
The process is five steps: connect your agent (GitHub recommended – it reads the code and builds a simulation environment, or MCP with one pasted prompt into Claude Code, Codex, Cursor or VS Code), simulate, audit, report, and badge. Repositories with an AGENTS.md are picked up automatically, and the vendor stresses it only reads what you connect – code and prompts stay with you. Audits are judged by an outside panel rather than self-scoring, and the finished report comes with an ‘Audited by iFixAi’ badge on higher tiers. The positioning is deliberately B2B and B2A – sold to enterprises and, unusually, to agents themselves.
Pricing is the weak spot for buyers: four tiers (Startup 85 inspections/mo and 2 agents, Growth 200 and 4, Enterprise 400 and 8, Agentic Enterprise 400 with unlimited agents and custom quote) are billed per agent per month with volume discounts, but no dollar figures are published anywhere on the site. The free option is real though: an Apache 2.0 open-source engine, self-hosted with your own model keys, covering 60 inspections with community support – and it has traction, with 16.7k GitHub stars and a Trendshift Python #1 Repository of the Week badge.
My verdict: iFixAi is attacking the right problem at the right time – agent authority and honesty, not just accuracy – with a credible taxonomy and zero-friction connection story. The open-source engine makes evaluation easy and free. The hesitations: unpublished SaaS pricing, a young vendor with no named company or team on the site, and audit quality that cannot be judged without running one. Start with the open-source engine on a real agent; the paid tiers will prove or price themselves from there.
Desk research only. This listing was compiled on September 30, 2026 from iFixAi's official website: the homepage (problem framing, five audit dimensions, the 64+ misalignment categories, the five-step process, why-iFixAi positioning and the full pricing section) plus its public Product Hunt and GitHub listings. No hands-on audit was run and no trial account, demo or vendor interview was conducted. Paid tier prices are not published on the site - only inspection volumes and agent counts - so no pricing figures are reported here. The customer-support-agent scenario on the homepage is labelled illustrative by the vendor; GitHub star counts and the Trendshift badge are third-party metrics shown on the vendor's site.
iFixAi does not publish a public changelog. Current site state: hosted audit service in four paid tiers (inspection counts published, prices not), a free Apache 2.0 open-source engine on GitHub (16.7k stars, Trendshift Python #1 Repository of the Week), and connection via GitHub or MCP. (Source: ifixai.ai)
| Pricing | Free+Paid |
|---|---|
| Free plan | Yes |
| Free trial | No |
| Pricing page | View pricing |
| API | No |
| Apps Insight Score | 38/100 |
| Implementation | Easy |
| Learning curve | Intermediate |
Editorial points are assigned by AppsInsight editors and cannot be purchased or influenced.
| Feature | iFixAi | Grain | OpenClaw | Decagon |
|---|---|---|---|---|
| Rating | 3.8 / 5 | 5.0 / 5 | 5.0 / 5 | 5.0 / 5 |
| Pricing | Free+Paid | Free plan | — | — |
| Starting price | — | Free | — | — |
| Free plan | Included | Included | No | No |
| Free trial | No | No | No | No |
| Platforms | — | Web app, Browser extension, iOS (iPhone & iPad), Android, macOS, Windows, Linux | macOS, Windows, Linux | Web app |
| Best for | Teams deploying AI agents with real authority over money, data or customers, engineering leads who need audit evidence they can defend, and enterprises that want agent governance without building an eval harness. | Sales teams, customer success teams, founders, agencies, ops teams, AI-first teams | Developers, solo founders, technical operators, AI enthusiasts, marketing agencies, SMB teams, support teams, internal ops teams | Enterprise SaaS teams, CX operations leaders, customer support automation teams, product-led companies, ops-heavy support organizations |
0 /mo
AI notetaker for teams that turns meetings into usable context
AI dictation that cleans up speech in any app
One AI-powered workspace where creative teams keep projects, conversations, reviews and work connected
One AI teammate runs your social media, influencer campaigns and PR in any language and market
Every social platform, client workspace and AI agent in one operating system
AI social media scheduler that learns your brand voice, with MCP, CLI and 10-platform publishing
No reviews yet. Be the first to review this app.
Already have an account? Log in to track your reviews.